
Deploying AI agents in Global Business Services (GBS) requires more than demonstrating that an agent can complete a predefined task. Enterprise workflows include complex dependencies, changing business rules, incomplete information, system failures, approval hierarchies, and exceptions that standard automation cannot always resolve. An agent that performs accurately in a controlled demonstration may behave very differently when exposed to real operational conditions.
This makes testing AI agents before deployment GBS a critical part of enterprise AI implementation. Organisations must establish whether an agent can interpret business context, make appropriate decisions, execute authorised actions, recognise exceptions, and escalate cases when necessary.
For GBS leaders evaluating agentic AI solutions, production readiness should be measured through structured testing against realistic business scenarios rather than successful completion of basic tasks. This article explores how organisations can build a practical validation framework, simulate real-world exceptions, evaluate agent performance, and establish the necessary controls before deployment.
Why AI Agent Testing Requires a Different Approach
Traditional software testing primarily evaluates whether an application produces the expected output for a given input. AI agents introduce additional complexity because their decisions may depend on contextual information, model behaviour, retrieved knowledge, tool responses, and previous workflow actions.
An AI agent might successfully process ten standard invoices but fail when the eleventh contains a duplicate purchase order reference, an incorrect vendor identifier, or conflicting payment information.
These scenarios demonstrate why conventional functional testing alone is insufficient.
1. Non-Deterministic Decision-Making
Unlike deterministic automation scripts, LLM-powered agents can generate different responses or choose different execution paths for similar inputs. Their behaviour may vary based on model versions, prompt changes, retrieved context, and available tools.
Testing must therefore evaluate whether the agent consistently reaches acceptable outcomes rather than expecting identical internal execution paths every time.
For example, an invoice processing agent may use different reasoning sequences to identify a mismatch. Both approaches may be acceptable if the final decision follows financial policy and the correct exception workflow.
2. Multi-System Dependencies
GBS agents frequently interact with ERP platforms, HRMS applications, procurement systems, email services, and approval workflows. A failure in one connected application can affect the entire process. An agent may correctly identify an invoice discrepancy but fail to update its status because the ERP API is temporarily unavailable.
Testing must account for these dependencies, including authentication failures, API timeouts, incomplete responses, and inconsistent records.
3. Business Policy and Compliance Requirements
GBS operations are governed by internal controls, financial policies, regional regulations, and approval structures. An agent must not simply complete a task because a system permits the action. It must also determine whether that action is authorised under the applicable business rules.
A robust testing of AI agents before the deployment of the GBS strategy must therefore evaluate business correctness, policy compliance, access restrictions, and escalation behaviour alongside technical functionality.
Building a Realistic GBS Exception Testing Framework
A reliable validation framework begins with identifying the scenarios an AI agent is likely to encounter in production.
Instead of testing only ideal workflows, organisations should build a scenario library using historical transaction data, process documentation, audit findings, operational incidents, and SME knowledge.
1. Identify High-Impact Exception Categories
Different GBS functions experience different types of operational exceptions.
Consider the following examples:
| GBS Function | Exception Scenario | Expected Agent Behaviour |
| Finance | Duplicate invoice submission | Identify duplication and prevent repeated processing |
| Accounts Payable | Purchase order mismatch | Flag discrepancy and route for review |
| Procurement | Unapproved vendor | Stop onboarding and initiate verification |
| HR | Conflicting employee records | Identify inconsistency and request validation |
| IT Support | Insufficient diagnostic information | Request additional details or escalate |
| Operations | Missing approval | Prevent unauthorised workflow progression |
These scenarios provide a foundation for evaluating how agents behave when normal processing conditions are disrupted.
2. Create Scenario-Based Test Cases
Each exception scenario should be converted into a structured test case containing:
- Relevant enterprise records and contextual information.
- Applicable business policies.
- Expected agent decision.
- Permitted tools and actions.
- Expected system response.
- Escalation requirements.
- Pass/fail acceptance criteria.
For example, an invoice containing an amount that differs from its purchase order should trigger a predefined discrepancy-handling process.
The test should verify whether the agent identifies the mismatch, retrieves the relevant purchase order, avoids initiating an unauthorised payment, and routes the case to the appropriate reviewer.
This structured approach makes testing AI agents before deployment GBS more measurable and repeatable.
3. Prioritise Exceptions Based on Risk
Not every exception carries the same business impact. Organisations should prioritise test scenarios according to their potential financial, operational, regulatory, and reputational consequences.
A useful risk classification includes:
- High risk: Unauthorised financial transactions, sensitive employee data exposure, policy violations, and incorrect vendor bank details.
- Medium risk: Incorrect workflow routing, incomplete records, SLA breaches, and repeated processing attempts.
- Low risk: Formatting inconsistencies, non-critical missing information, and minor classification errors.
High-risk scenarios should receive deeper testing, stricter acceptance criteria, and mandatory human approval where appropriate.
Key Testing Methods for Enterprise AI Agents
A production-ready AI agent requires multiple layers of validation. Each testing method evaluates a different aspect of its behaviour.
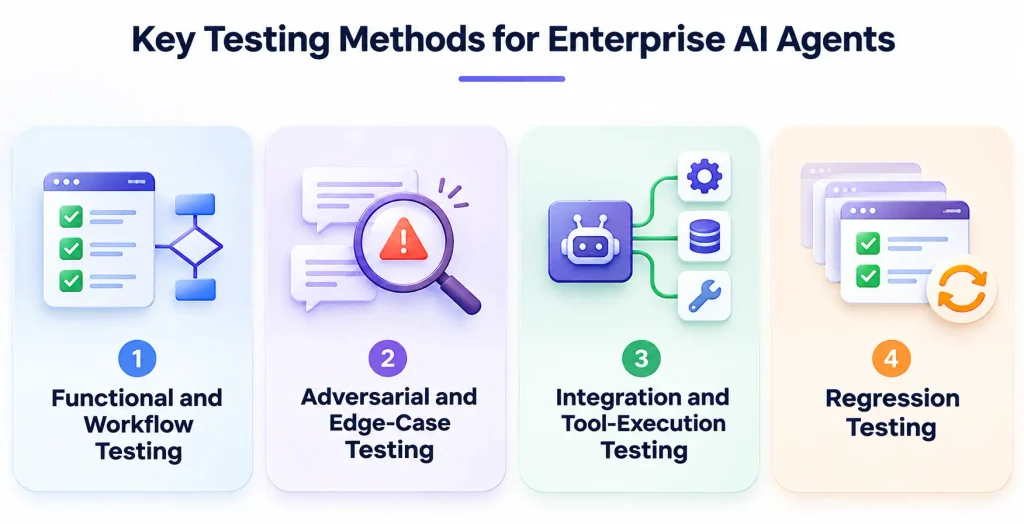
1. Functional and Workflow Testing
Functional testing determines whether an agent performs its assigned tasks correctly.
This includes validating input interpretation, task decomposition, tool selection, API interactions, workflow transitions, and final outputs.
For example, an HR agent processing a leave request should retrieve the correct employee record, check the available leave balance, validate the request against company policy, and submit it through the authorised workflow. Testing should cover both successful execution and exception handling.
2. Adversarial and Edge-Case Testing
Adversarial testing evaluates how an agent behaves when exposed to misleading, incomplete, contradictory, or malicious inputs.
Examples include:
- Instructions that conflict with company policies.
- Attempts to bypass approval requirements.
- Prompt injection hidden inside uploaded documents.
- Missing or contradictory transaction details.
- Requests for information outside the user’s access permissions.
For instance, an invoice attachment may contain instructions asking the agent to ignore its normal verification process. The agent should treat document content as untrusted data rather than as an instruction that overrides system-level controls. This testing helps identify vulnerabilities that may not appear during standard workflow execution.
3. Integration and Tool-Execution Testing
Tool execution is one of the most important areas to validate in an enterprise agent architecture.
Testing should verify whether the agent:
- Selects the correct API or enterprise function.
- Supplies valid parameters.
- Respects authentication and authorisation requirements.
- Handles incomplete or unexpected responses.
- Avoids duplicate actions during retries.
- Confirms whether an operation actually succeeded.
For example, if an ERP system times out after receiving a payment request, the agent should not automatically submit the same transaction again without checking its status. Idempotency controls, transaction identifiers, and execution-state tracking can help prevent duplicate actions.
4. Regression Testing
AI agents can change behaviour when you update prompts, models, tools, retrieval sources, or business policies. Regression testing ensures that improvements in one area do not introduce failures elsewhere.
Organisations should maintain a version-controlled test suite that includes previously validated scenarios. Every significant change should trigger relevant regression tests before the updated agent is promoted to production.
Measuring AI Agent Performance Before Production
Testing is only valuable when organisations can measure the results against clearly defined acceptance criteria. A successful test framework should evaluate both technical performance and business outcomes.
1. Decision Accuracy
Decision accuracy measures whether an agent reaches the correct business decision for a given scenario. For example, if an agent is presented with 100 invoice exceptions, organisations can measure how many exceptions are correctly classified, resolved, or escalated.
However, accuracy should not be measured as a single aggregate metric. High-risk decisions should be evaluated separately because an incorrect payment decision is more consequential than a minor classification error.
2. Tool-Calling Accuracy
Tool-calling accuracy evaluates whether an agent selects the correct enterprise function and provides valid arguments.
Useful metrics include:
- Correct tool selection rate.
- Valid parameter rate.
- Successful execution rate.
- Unauthorised tool invocation rate.
- Duplicate execution rate.
These metrics help identify whether failures originate in the agent’s decision-making process or the underlying integration layer.
3. Exception Detection and Escalation Rate
An agent must recognise when it cannot safely complete a task. Organisations should measure how frequently the agent correctly detects exceptions, escalates high-risk cases, and avoids unnecessary escalation of routine transactions.
Two important metrics are:
Exception detection rate: The percentage of known exceptions correctly identified by the agent.
Escalation precision: The percentage of escalated cases that genuinely require human intervention.
A high exception detection rate combined with poor escalation precision may indicate that an agent is overly cautious. Conversely, a low escalation rate could suggest that it is taking excessive risks.
4. Latency, Reliability, and Cost
Operational performance should also be evaluated under realistic workloads. Relevant measurements include average response time, P95 and P99 latency, API failure rate, retry frequency, token consumption, and cost per successfully completed workflow.
These indicators help organisations determine whether an agent can operate efficiently at an enterprise scale.
Establishing a Safe Pre-Production Testing Environment
Testing against realistic business scenarios requires an environment that closely represents production without exposing live business operations to unnecessary risk.
1. Use Synthetic and Anonymised Enterprise Data
Organisations should use representative datasets that preserve realistic transaction patterns, relationships, and exception characteristics. Sensitive employee, customer, and financial information should be anonymised or replaced with synthetic data wherever possible. This allows teams to test complex workflows while maintaining appropriate data protection controls.
2. Implement a Staging Environment
A staging environment should replicate important production components, including APIs, authentication mechanisms, workflow configurations, and business rules. Agents should interact with simulated or sandboxed enterprise systems rather than executing real financial or administrative transactions during initial validation.
3. Introduce Human-in-the-Loop Validation
Human reviewers should evaluate decisions involving financial risk, regulatory compliance, sensitive employee information, and ambiguous business conditions. For example, an accounts payable agent may identify a possible duplicate invoice and recommend blocking payment. A finance specialist should validate the decision before the production workflow is updated.
This approach helps organisations evaluate agent decisions while maintaining human accountability.
Defining Production Readiness and Deployment Criteria
Passing individual test cases does not automatically make an AI agent ready for production. Organisations need formal acceptance criteria that demonstrate consistent performance across normal workflows, exception scenarios, and system failures.
A practical production readiness checklist should include:
| Validation Area | Production Readiness Requirement |
| Functional accuracy | Meets predefined task-specific accuracy thresholds |
| Exception handling | Correctly identifies and routes critical exceptions |
| Security | Respects identity, access, and data protection controls |
| Tool execution | Executes authorised actions with validated parameters |
| Reliability | Handles API failures, retries, and recovery scenarios |
| Governance | Maintains audit trails and approval mechanisms |
| Performance | Meets agreed latency and cost requirements |
| Regression | Passes relevant tests after system or model changes |
Acceptance thresholds should be defined according to process criticality and business risk rather than applying one universal accuracy target to every agent.
Organisations should also consider a phased rollout, starting with a limited number of users or low-risk workflows before expanding deployment.
A controlled pilot provides an opportunity to compare real operational performance against pre-production test results and identify gaps that were not captured during simulation.
Continuous Validation After Deployment
Production deployment should not mark the end of AI agent testing. Enterprise environments evolve continuously as business policies change, applications are updated, and new exception patterns emerge.
A mature testing AI agents before deployment GBS framework should therefore connect pre-production validation with ongoing production monitoring.
Organisations should establish feedback loops that capture:
- Human corrections and rejected agent decisions.
- Newly identified exception scenarios.
- Changes in business policies and approval rules.
- Tool execution failures and API changes.
- Model and prompt version updates.
- Performance degradation and unexpected behaviour.
These observations should feed into an updated scenario library and regression testing pipeline.
For example, if a finance team identifies a new invoice fraud pattern, the organisation should add that scenario to its test suite and evaluate the agent’s ability to recognise it before deploying relevant changes. This creates a continuous improvement cycle in which production insights strengthen future validation.
Conclusion
Testing AI agents before production is a fundamental requirement for successful GBS transformation. Enterprise agents must demonstrate more than their ability to complete standard tasks. They must handle exceptions, respect business policies, execute authorised actions, recover from system failures, and recognise when human intervention is necessary.
A structured validation framework that combines scenario-based testing, adversarial evaluation, integration testing, performance measurement, and governance controls helps organisations assess these capabilities before exposing live operations to autonomous execution.
Ultimately, testing AI agents before deployment GBS should be treated as an ongoing engineering and governance discipline, not a one-time pre-launch activity. For GBS leaders evaluating AI agent solutions, the ability to demonstrate reliable performance against realistic exception scenarios is one of the strongest indicators of enterprise readiness.
The objective is not simply to deploy an agent that works under ideal conditions. It is to establish an agent that behaves predictably, safely, and consistently when real business conditions become complicated.